
NeuroLibre is a platform for ‘reproducible publications’ that packages the code, data, and runtime environments necessary to produce in-browser executable research objects, including articles, tutorials, and reports. NeuroLibre publications integrate scientific narratives, figures, and code with the software environment and computational hardware required to run that code. This offers a more flexible approach to publishing academic research, complements static research articles, and facilitates the communication of scientific results by producing open and reproducible publications with FAIR access to all its constituents.
Its successor, Evidence, is built by the same team on the same principles and extends the model to all the sciences. Evidence is in public beta; submissions continue through NeuroLibre.
What needs and problems does NeuroLibre address?
A key concept in scientific practice is the critical examination of our work by peers. However, despite near-universal agreement on the necessity of peer review, flaws in this system have led to broad disillusion and dissatisfaction with the review process and the associated interactions with the traditional publishing system.
One issue is the failure by authors to provide the minimum requisite information for reviewers and the broader community to:
- replicate the work independently
- readily access the elements (data, analysis scripts, graph generation, etc.) necessary to adequately evaluate the work in terms of method, analysis, etc.
- evaluate the validity of conclusions
These are essential to peer review and yet the mainstream approach to publication rarely provides them. When added to other flaws such as publication bias and accessibility concerns (e.g., exclusionary costs, open availability of publicly-funded research, etc.), a cascade of consequences results, including low levels of study replication and the associated waste of public resources, leading to diminished scientific discovery and downstream societal impact.
NeuroLibre addresses this problem by providing a free platform that enables robust peer review and study replicability through a new paradigm in scientific publishing.
What does a NeuroLibre publication look like?
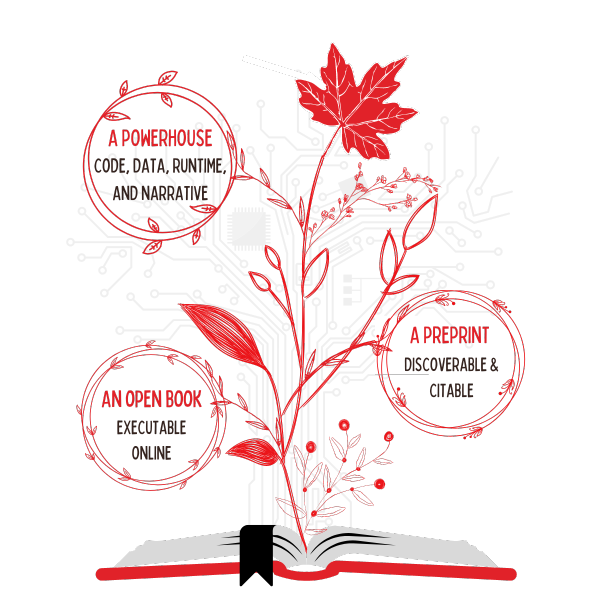
A NeuroLibre publication can be anything from supplementary materials for a main article published elsewhere to a complete, full-length paper that is augmented with interactive elements and contains everything necessary for full reproducibility.
Some key features of a NeuroLibre publication are:
- easy, freely accessible, in-browser display of the publication and links to all its underlying resources (data, scripts, etc.)
- a downloadable, fully formatted PDF version of the publication, registered as scholarly content by Crossref (citable and discoverable) and discoverable through scholarly search engines such as Google Scholar
- Zenodo archives and DOIs for the publication’s
- data
- executable book (a collection of Jupyter Notebooks or MyST documents)
- Docker image (the full software environment needed to run the code), also available from a public container registry
- code repository
- the ability to spawn a temporary, modifiable, and re-executable instance of the publication, all from a browser interface for real-time exploration of the findings
- a Dimensions badge, active from the moment of NeuroLibre publication to keep track of the citation counts
Wired papers
Some publications go further: they are wired to their evidence. In a wired paper, the figures are live connections to the data and analyses behind them, so a reader’s action on a figure changes the result being reported. In NeuroLibre’s first wired paper, Strong Coupling of Retinal Thickness and Optic Nerve Myelin in Vivo (Plante et al., 2026), by authors from Polytechnique Montréal and NYU Abu Dhabi, a reader can remove individual participants from a regression and watch the fit change, and every result opens into the notebook that produced it.
Evidence: beyond neuroscience
NeuroLibre was built for neuroscience, but its technology was never specific to it, and its corpus already includes a paper in physics and an essay on the history of science. Evidence, its successor, is built by the same team on the same principles to serve all the sciences. Evidence is in public beta and is not yet open for submissions. Until it is, submissions continue through NeuroLibre. Its documentation is at docs.evidencepub.io. Evidentron, the platform’s AI assistant, lets readers question a publication and its data in plain language (demonstration).
Open standards, national infrastructure
- Open formats. NeuroLibre publications are written in MyST Markdown, the community standard of the Jupyter Book ecosystem. All 21 published papers are now in MyST, and the team contributes improvements back to that open-source toolchain. It also takes part in the Continuous Science Foundation‘s work with openRxiv on the Open Exchange Architecture, a shared standard for moving scientific articles, with their data and code, between writing and publishing tools.
- Canadian infrastructure. The platform runs on the Arbutus cloud of the Digital Research Alliance of Canada. It is defined entirely in code, so it can also be deployed on other infrastructure worldwide.
- Archived and runnable. Every re-executable publication archives its paper, data, container image and code as separate Zenodo DOIs (more than 70 for 21 publications), and every published environment can also be pulled from a public container registry (registry.evidencepub.io).
- Connected to the CONP Portal. The Portal datasets derived from NeuroLibre publications link directly to them, with a badge showing the type of publication and a sort option that places them first.
What can NeuroLibre do for me?
Solidifying your work before sharing it with the community, thereby also making acceptance in a traditional journal more likely
Given prevalent ‘publish or perish’ incentive structures in research environments, most researchers’ primary strategic, career-building objective is producing (static PDF) publications through traditional publishers, preferably in high-impact journals.
As a community, we urgently need to broaden our criteria for the evaluation of a researcher’s contributions to science, this being among the wider objectives of Open Science. The creation of a NeuroLibre publication concurrently serves these types of reforms and the traditional objective of a high-impact publication by:
- creating a structured checklist of the key elements needed to ensure your research conforms to best practices prior to publication
- allowing for open community feedback that may lead to improvement of the manuscript and/or the underlying work before reaching the traditional review process, thereby making acceptance in a traditional journal more likely
- demonstrating clear transparency and confidence to the community and reviewers even before they start reading
- making it easier for you, your peers, and potential reviewers, to track, modify, archive, and reproduce your work
Making your publication’s resources truly FAIR
Sure enough, sharing is better than no sharing, but the typical manner in which resources are shared is far from faithful to the FAIR principles (Findability, Accessibility, Interoperability, and Reusability). Data are not FAIR or democratized if they are difficult to find, parse, understand, or reuse. Some common examples of well-intentioned but poorly executed sharing include:
- data that are posted on the OSF, Zenodo, or other popular repository, but are hastily assembled into a ZIP archive with non-standard, ill-described, and non-searchable content
- code that is posted on GitHub or elsewhere, but lacks essential documentation and information about dependencies and execution
- code and data that are shared but are so computationally demanding that it is unrealistic for anyone to run the tasks on typical hardware
NeuroLibre addresses these kinds of difficulties by providing the environment and archived, versioned resources necessary to fully reproduce your work, as described in the above section “What does a NeuroLibre publication look like”. Further details, including parts of the workflow that lead to the creation of the components of a NeuroLibre publication, are found in the NeuroLibre section of this paper.
What are the requirements for a NeuroLibre publication?
- A public code repository that has a single or a collection of Jupyter Notebooks and/or MyST markdown files.
- A public data repository needed to generate the outputs (typically figures) from the executable part of your content.
- Reproducible runtime configurations recognized by BinderHub.
- A BibTeX formatted bibliography (paper.bib) and author information (paper.md).
For guides on preparing a NeuroLibre submission, see the NeuroLibre documentation.